Data, GPUs and Deep Learning
In 2012, AlexNet showed what could happen when neural networks, large datasets, GPUs and improved training methods came together—helping ignite the deep-learning era.
The Road to Artificial Intelligence — Part 10 of 15
WHEN COMPUTING POWER MET DATA
The revival of neural networks had renewed interest in connectionist approaches. Then, in 2012, a computer vision system delivered a major improvement in a widely watched image-recognition competition, bringing renewed attention to neural networks.
The system became known as AlexNet. It was neither a sudden invention nor the origin of deep learning. Its success grew from a convergence of large labeled datasets, a demanding benchmark, faster processors, better software, older neural-network ideas, and careful engineering.
The story is not that one model appeared. It is how developments that had been separate became useful together.
Neural networks before AlexNet
Convolutional neural networks did not begin in 2012.
Researchers had already explored systems that recognize visual patterns hierarchically. Fukushima's neocognitron was an important precursor, and Yann LeCun and colleagues demonstrated convolutional networks for document recognition in the 1990s. These systems used ideas that later became familiar: local connections, shared weights, and layers that built increasingly complex representations.
Their practical reach, however, was constrained by the amount of training data and computing power available at the time. The challenge went beyond inventing a new architecture. Researchers had to make large networks train effectively on difficult, realistic datasets.
ImageNet turns recognition into a measurement
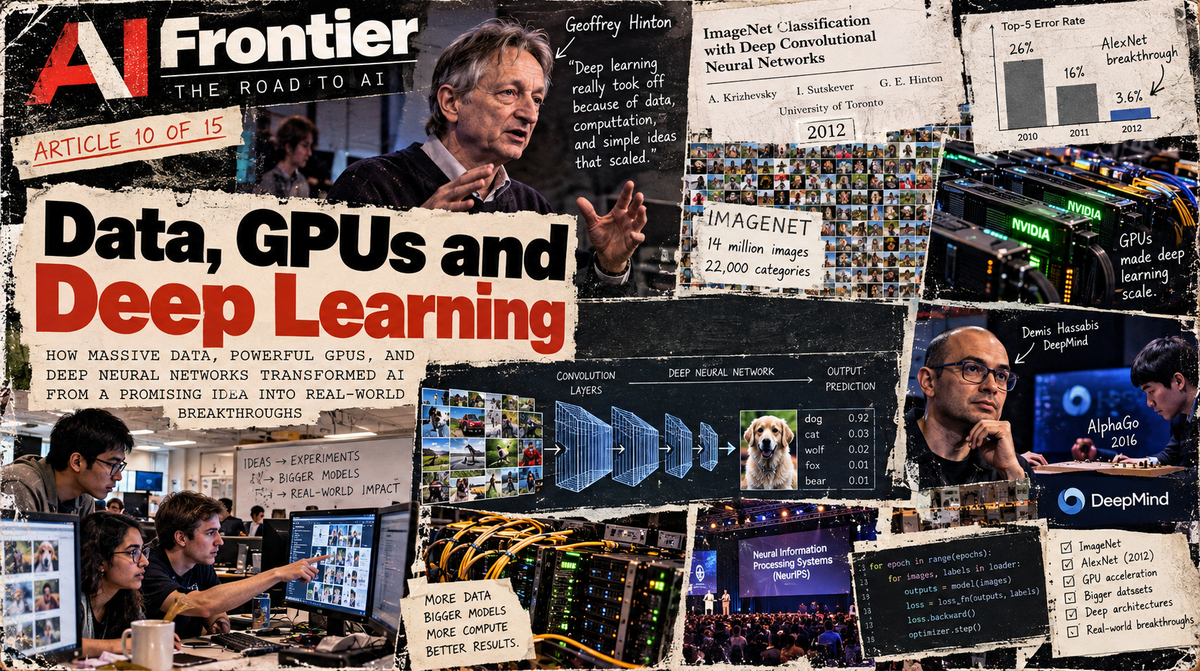
A crucial step came in 2009 with ImageNet, a large image database organized around WordNet concepts. Its paper reported 3.2 million images across 5,247 synsets and 12 WordNet subtrees, collected from the internet and checked through a mix of human review and crowdsourced annotation.
ImageNet mattered for two reasons. It supplied far more labeled examples than earlier vision datasets, and it helped establish a shared way to measure progress. Its annual contest, the ImageNet Large Scale Visual Recognition Challenge, turned part of that resource into a standardized task: classifying images across 1,000 categories. Instead of reporting results on unrelated datasets with different rules, researchers were competing on common ground.
The benchmark begins to expose a gap
The first ImageNet challenge took place in 2010, with NEC-UIUC listed as the winner across 1,000 categories and roughly 1.2 million training images. In 2011, XRCE won with a reported flat-classification cost of 25.770%.
These early results did not yet suggest a major shift, but the contest created a visible target for measuring progress. Each year, researchers could see whether a method had made a real difference.
Benchmarks don't measure everything. They can't establish general intelligence, reliability in unfamiliar settings, or safety in real-world use. At the time, ImageNet provided researchers with a demanding, repeatable benchmark for comparing progress.
GPUs become useful for neural networks
Meanwhile, graphics processors were becoming programmable for purposes beyond displaying images.
Researchers had already tried GPUs on neural networks. Chellapilla and colleagues demonstrated GPU-accelerated convolutional networks in 2006, and Raina and collaborators studied large-scale deep learning on GPUs in 2009. In 2011, Cireșan and colleagues reported strong results from GPU-trained convolutional networks on datasets including MNIST, CIFAR-10, and NORB.
GPUs were originally designed primarily for graphics workloads, but their ability to perform many similar numerical operations in parallel made them increasingly useful for neural-network training. Its value came from performing many similar numerical operations in parallel, exactly the kind of calculation repeated throughout neural-network training. Training was still far from effortless, and programming a large network took serious technical work. But GPUs changed the scale of experiments researchers could attempt.
Other fields were making progress too
Computer vision wasn't developing in isolation.
In speech recognition, deep neural networks were already beating traditional Gaussian mixture acoustic models on several benchmarks, as Hinton and colleagues documented in a 2012 survey. Elsewhere, Banko and Brill's 2001 study showed how strongly performance on one natural-language task could improve as the amount of training data increased. It reinforced a broader lesson: performance depends not only on the model, but also on the quantity and quality of the data behind it.
Training deep networks was still difficult
Optimization problems had long held deep networks back.
In deep networks, activation functions such as sigmoids could cause learning signals to become extremely small as they passed backward through many layers, making training difficult. Glorot and Bengio's 2010 work examined these difficulties, along with the importance of initialization and activation functions.
Researchers were also looking for ways to reduce overfitting and keep networks from leaning too heavily on particular internal features. Dropout became one influential technique for reducing overfitting by randomly leaving out some units during training, making the network less dependent on particular internal features.
AlexNet brought several such ideas together. It used rectifying nonlinearities, data augmentation, and dropout. AlexNet's performance did not depend on a single innovation. Its strength came from combining these techniques in a large convolutional network trained on a large dataset with substantial computing power.
The 2012 result
The AlexNet paper described a network with five convolutional layers, roughly 60 million parameters, and about 500,000 neurons. It was trained on two GPUs, which took five to six days according to the paper.
In the ImageNet contest, the official results page lists the SuperVision entry at 15.315% top-five error when additional Fall 2011 ImageNet data was used. Using only the supplied training data, the listed result was 16.422%. The commonly cited 15.3% figure came from the competition entry using additional ImageNet data, while the paper reported separate results for individual networks and ensembles.
The runner-up, ISI, recorded 26.172% top-five error, so the gap between the two official entries was 10.857 percentage points. The size of the improvement showed what became possible when convolutional networks were combined with large labeled datasets, GPU computation, and carefully engineered training methods. A technique that had existed for years became far more effective when paired with a large benchmark, extensive labeled data, GPU computation, and a carefully engineered training system.
What happened next
The result didn't stay isolated.
By 2013, deep-learning systems had become much more prominent in the ImageNet competition, as researchers refined network architectures and training methods. Other researchers refined the architecture, improved training methods, and found better ways to visualize what the networks had learned. Older approaches remained important, and different research communities adopted neural networks at different rates.
Even so, the field's center of gravity had shifted. ImageNet offered evidence that large convolutional networks could perform extremely well on a difficult visual-recognition benchmark.
The connection to AI
AlexNet's importance lies less in any single architectural novelty than in demonstrating what became possible when several existing ideas and resources came together. Several ingredients had to line up:
- Data: ImageNet supplied millions of labeled examples.
- Benchmarking: The ImageNet contest made progress visible and comparable.
- Hardware: GPUs made large numerical computations practical.
- Software and implementation: Better tools and implementations made it possible to build and train increasingly large models.
- Architecture: Convolutional networks suited images.
- Optimization: ReLUs, dropout, augmentation, and other techniques helped training succeed.
- Engineering: The system had to make all of these pieces work together.
AlexNet illustrated a recurring pattern in AI: established ideas can become far more effective when combined with new resources, better measurement, and improved implementation.
AlexNet's success emerged from particular technical choices, research institutions, available resources, and years of earlier work rather than from an inevitable path toward deep learning. Strong performance on ImageNet did not demonstrate broad intelligence. Recognizing objects in benchmark images is a narrower skill than understanding the world, reasoning reliably, or acting safely in complex environments.
Looking ahead
AlexNet changed which approaches seemed practical and encouraged researchers to build larger neural networks around increasingly powerful computing and growing datasets.
The next article follows the deep-learning surge after 2012, as neural networks advanced in vision, language, game playing, and prediction.
SOURCES
- Michele Banko and Eric Brill, "Scaling to Very Very Large Corpora for Natural Language Disambiguation," Proceedings of the 39th Annual Meeting of the Association for Computational Linguistics, 2001. https://aclanthology.org/P01-1005/
- Xavier Glorot and Yoshua Bengio, "Understanding the Difficulty of Training Deep Feedforward Neural Networks," Proceedings of AISTATS, 2010. https://proceedings.mlr.press/v9/glorot10a.html
- Jia Deng et al., "ImageNet: A Large-Scale Hierarchical Image Database," CVPR, 2009. https://www.image-net.org/static_files/papers/imagenet_cvpr09.pdf
- Alex Krizhevsky, Ilya Sutskever and Geoffrey E. Hinton, "ImageNet Classification with Deep Convolutional Neural Networks," Advances in Neural Information Processing Systems 25, 2012. https://papers.nips.cc/paper/4824-imagenet-classification-withdeep-convolutional-neural-networks.pdf
- ImageNet organizers, "ImageNet Large Scale Visual Recognition Challenge 2010." https://www.image-net.org/challenges/LSVRC/2010/
- ImageNet organizers, "ImageNet Large Scale Visual Recognition Challenge 2011 — Results." https://www.image-net.org/challenges/LSVRC/2011/results.php
- ImageNet organizers, "ImageNet Large Scale Visual Recognition Challenge 2012 — Results." https://www.image-net.org/challenges/LSVRC/2012/results.html
- Dan Claudiu Cireşan et al., "Flexible, High Performance Convolutional Neural Networks for Image Classification," IJCAI, 2011. https://mlanthology.org/ijcai/2011/ciresan2011ijcai-flexible/
- Geoffrey Hinton et al., "Deep Neural Networks for Acoustic Modeling in Speech Recognition," IEEE Signal Processing Magazine, 2012. Google Research publication page.
- Olga Russakovsky et al., "ImageNet Large Scale Visual Recognition Challenge," International Journal of Computer Vision, 2015. https://arxiv.org/abs/1409.0575